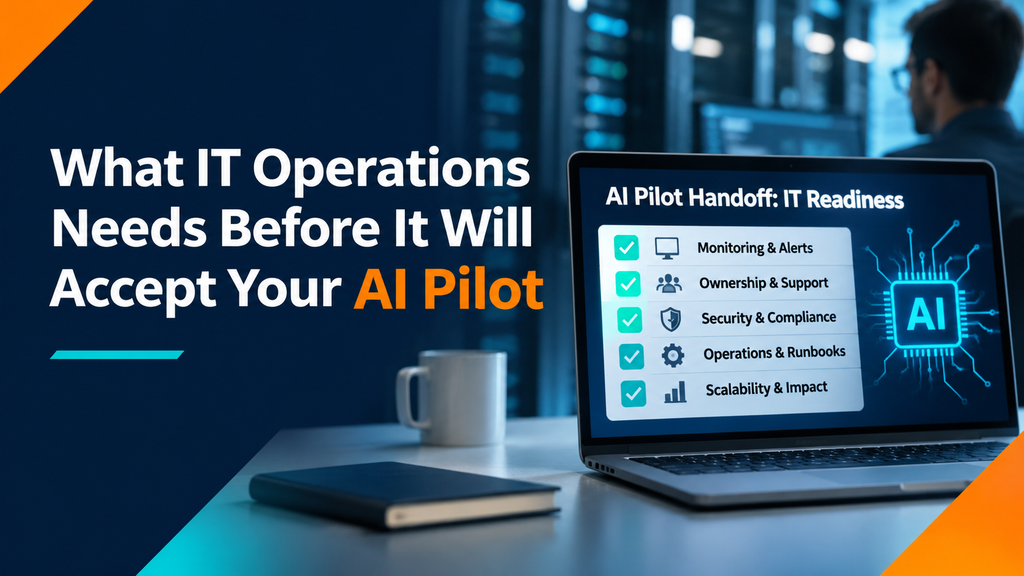
Quick answer: IT operations should not accept an AI pilot without a separate handoff deliverable: documented architecture, access controls, a named on-call owner, defined failure behavior, and a rollback path. Treat the handoff as its own project, not an afterthought to a demo that worked.
A pilot that works in the demo is not a deliverable. The handoff to IT operations is a separate deliverable, and a team that skips it is asking operations to own something it has never documented, tested, or signed off on. When that handoff never happens, operations can reasonably decline to support the pilot in production, and the project stalls with no one willing to say why.
The pilot and the handoff are two different projects
Treat them as two line items, not one. The pilot proves the idea works under supervision, with the innovation team or an outside vendor watching the output and correcting mistakes as they happen. The handoff is the work of making that same process survive without supervision: documented, monitored, owned, and reversible. A pilot plan with no handoff section is an incomplete plan, not a finished one.
This distinction matters because budget and timeline get set at the start of a project, before anyone has thought hard about what operations will need. Checklist point 9 calls this out directly: pilot funded, rollout unfunded is a common reason a pilot works and then goes nowhere. Ask the question at kickoff, not after the demo: who owns this in production, and what do they need in order to say yes?
What the runbook must contain
Reject a handoff that is a verbal walkthrough plus a shared document with partial notes. A runbook is a written artifact operations can use without the original builders in the room. At minimum it names:
– The architecture: which systems the AI reads from, which systems it writes to, and where the model or agent itself runs.
– The data flow: what triggers a run, what inputs it needs, and what output it produces.
– The access controls: which accounts, credentials, and permissions the process uses, and who is authorized to change them.
– The known failure modes observed during the pilot, however small, and what was done about each one.
Require this in writing before you accept ownership. A system that is not described on paper cannot be fixed reliably during an incident.
Name one on-call owner, not a team
Checklist point 6 asks for one accountable business owner and a technical counterpart. Apply the same rule to the handoff itself. A rotating on-call list with no single accountable person means the first incident becomes a debate about whose job it was, instead of a fix.
Name one person. Give that person the authority to pause the process, roll it back, or escalate without asking permission first. If the pilot team cannot name this person before handoff, the handoff is not ready, no matter how well the demo went.
Define failure behavior before launch, not after
Ask the pilot team a direct question: what does this system do when it fails? Not whether it will fail. What happens when it does.
A defined failure behavior specifies what the process does when an API call times out, when input data is malformed, or when the model returns something outside expected bounds. It should fail safe: stop and alert, not guess and continue. Operations should see this behavior tested, not described in the abstract, before accepting the handoff.
Decide what gets monitored and who sees the alert
Require a monitoring plan in the runbook, not a promise to add one later. Name what is watched: whether the process ran, whether it errored, and whether its output falls inside the range the pilot team observed. Name where alerts go and who acknowledges them. An alert that lands in a shared inbox no one owns is the same as no alert. Ask the pilot team to show one alert firing in a test, end to end, from the signal to the named on-call owner’s phone or queue. If they cannot, the monitoring does not exist yet.
Rollback is not optional
A handoff needs a documented path back to the prior manual or legacy process. Write down how to disable the automation, who can authorize it, and how long it takes to take effect. If reverting means calling the original vendor and waiting on their schedule, that is not a rollback plan: it is a dependency.
Test the rollback before go-live, the same way the pilot itself was tested. A rollback that has never been exercised is a theory, not a plan.
Tie the handoff to ownership and budget, not just technology
The handoff checklist above is really checklist points 6 and 9 made concrete. Point 6 asks whether there is a named accountable owner; the on-call requirement is what that looks like once the process is in production. Point 9 asks whether there is budget and timeline for rollout, not just the pilot; the runbook, monitoring, and rollback plan are what that budget actually buys.
A team presenting a finished pilot without a named owner, a runbook, or a rollback path has not finished the project. It has finished the part that was easy to demo. Operations is right to say no until the rest of the work shows up.
Before you agree to accept the next AI pilot, score it against the AI Readiness Checklist, a 10-point scorecard that includes ownership and rollout budget and timeline. Do it before you say yes.
AI Readiness Checklist (10 points)
FAQ
What should IT operations require before accepting an AI pilot handed off from an innovation team or vendor?
A written runbook covering architecture, data flow, and access controls; a named on-call owner with authority to pause or roll back the process; defined failure behavior; and a tested rollback path back to the prior process.
Who should own an AI pilot once it moves into production?
One named accountable business owner plus a technical counterpart, per checklist point 6. A rotating team or a generic ‘IT owns it’ assignment is not a named owner.
Why do AI pilots stall after a successful demo?
One common reason is that budget and calendar time were allocated for the pilot but not for rollout support (checklist point 9). Without a funded handoff, operations may have nothing documented to accept.
Comments are closed